The pace of technological change has fundamentally altered what it means to lead effectively. While previous generations could build careers on expertise that remained relevant for decades, today’s leaders face a different reality: The technologies driving competitive advantage evolve at unprecedented speed.
AI, automation, and data analytics aren’t just changing how we work. They’re redefining leadership itself.
The leaders who will thrive aren’t those who can predict which technologies will dominate but those who develop the mindset to rapidly assess, adopt, and integrate new tools as they emerge. The question isn’t whether the next disruptive technology will arrive. It’s whether you’ll be ready when it does.
Digital Literacy Is Now Business Critical
For example, consider how cloud computing transformed entire industries within a decade, or how mobile technology shifted consumer expectations overnight.
Companies that dismissed these innovations as just the latest tech trends found themselves scrambling to catch up while more agile vendors increased their competitive advantage or took valuable market share. Today, AI represents the latest technology revolution, but unlike previous innovations, it touches every business function from marketing and sales to operations and finance.
The new baseline for effective leadership isn’t technical expertise. Instead, it’s digital fluency. This means understanding how emerging technologies can solve business problems, recognizing opportunities for automation and productivity improvements, and making informed decisions about technology investments.
Whether you’re managing a team of five or leading a Fortune 500 company, the ability to assess and integrate new tools has become as fundamental as financial literacy.
Stay Ahead: Build Your Tech Intelligence
The pace of technological change now means that yesterday’s cutting-edge solution quickly becomes today’s standard practice, or worse, obsolete. Leaders need to be proactive about staying informed rather than waiting for formal training programs or company initiatives. Simple steps like reading industry publications, following tech blogs, listening to webinars and podcasts, and joining professional networks focused on innovation trends can keep you ahead of the curve.
This doesn’t require becoming a technical expert. It’s about maintaining a mindset to recognize patterns of new technologies that could impact your industry. Regular exposure to technology news helps you identify emerging tools before they become mainstream and recognize when pilot programs might give your organization a competitive edge.
The AI Wake-Up Call: Timing Matters
What happens when leaders aren’t fully up to date with the latest technology trends?
The November 2022 launch of ChatGPT caught many companies completely off guard. Within months, a technology that few executives had seriously considered was transforming customer service, content creation, software development, strategic planning, and so many other processes across virtually every industry.
This pattern reveals a critical challenge: the difficulty of timing adoption correctly. Being too early means investing resources in unproven technologies that may not deliver immediate returns. Being too late means watching competitors capture market share while you’re still figuring out basic implementation.
As a result, most successful organizations monitor emerging technologies closely enough to move quickly when breakthrough moments occur but avoid the bleeding edge where costs are high and outcomes uncertain.
The AI revolution illustrates why staying informed about technology trends isn’t just helpful, it’s essential for survival. Leaders who had built even basic awareness of machine learning capabilities were better positioned to recognize the transformative potential of generative AI and respond strategically. In a world where technological breakthroughs can reshape markets overnight, the question isn’t whether you can afford to stay current with emerging technologies; it’s whether you can afford not to.
Data-Driven Decisions That Actually Drive Results
Here’s an example where more technology-aware executives can make an immediate impact: data-driven decision-making.
Most organizations claim to be doing this, but not all are using analytics to fundamentally transform how they operate. The difference between companies that merely collect data and those that turn information into competitive advantage lies in their approach to decision-making. Advanced analytics can reveal patterns invisible to traditional analysis, identify problems before they become costly, and uncover opportunities that intuition alone would miss.
Consider the difference between reviewing quarterly sales reports and using predictive analytics to identify which customers are likely to churn next month. One approach tells you what happened while the other empowers you to take action before problems materialize. Leaders who embrace sophisticated data analysis can make faster, more accurate decisions about everything from product development to resource allocation.
The most successful leaders don’t just consume data. They actively seek out analytics that challenge their assumptions. This means moving beyond basic reporting to embrace tools that can process vast amounts of information and provide actionable insights in real time. When data truly drives decision-making, organizations become more agile, more responsive to market changes, and ultimately, more profitable.
Build Your Future-Ready Approach
The leaders who will thrive in the coming decade share a common approach: They treat technological fluency as an ongoing discipline rather than a one-time learning event. The choice isn’t whether technology will continue to reshape how we work; it’s whether you’ll be leading that transformation or struggling to keep up with it.
They regularly consume technology news, experiment with new tools in low-risk environments, and maintain curiosity about how emerging innovations might solve current business challenges. Most importantly, they recognize that future-proofing leadership isn’t about predicting which specific technologies will dominate, but about building the adaptability to capitalize on whatever comes next.
The organizations that emerge strongest from each wave of technological change are those led by people who view innovation as an opportunity rather than a threat. These leaders create cultures where experimentation is encouraged, where data drives decisions, and where teams are prepared to pivot quickly when new possibilities arise.
At DataBank, we believe that being a great company means more than building world-class infrastructure. It means showing up for the communities where we live and work. That spirit was on full display recently at our DFW3 facility in Dallas-Fort Worth, where DataBankers, customers, and vendor partners came together for the DFW Metro Blood Drive.
A Small Event with a Big Impact
Hosted in partnership with Carter BloodCare, the drive drew donors from across the DataBank community. Carter BloodCare set up donation stations inside the facility and in mobile trucks and vans on site. To keep things festive, a taco truck was parked on site for anyone looking to fuel up before or after donating.
A DataBank employee donates blood in one of Carter BloodCare’s mobile units, part of the DFW Metro Blood Drive hosted at DFW3.
All told, 21 donors participated, with two giving double donations. The turnout speaks to the kind of workplace culture DataBank works hard to build. DataBankers across the country bring that same spirit to local blood drives in their own cities and markets, showing up throughout the year in recognition of an ongoing and critical need for blood donations.
What made the day even more meaningful was seeing that spirit extend beyond our own team. A DataBank vendor also joined employees to donate. When partners show up for something like this, it speaks to the kind of relationships worth building.
According to Carter BloodCare, a single donation can save up to three lives. With 21 donors and two double donations, what started as a four-hour event carries the potential to save dozens of lives.
A Tradition Worth Continuing
This wasn’t a one-time event. Last year, DataBankers joined the data center industry’s annual #DataCenterSleevesUp campaign, a virtual blood drive organized by the Data Center Coalition in partnership with the American Red Cross and Vitalant.
A DataBank employee donates blood inside DFW3, one of 21 donors who participated in the DFW Metro Blood Drive hosted in partnership with Carter BloodCare.
That spirit carried right into this year’s DFW Metro Blood Drive, and we’re proud to keep building on it.
About DataBank Cares
DataBank Cares is our companywide commitment to corporate social responsibility, supporting the employees, communities, and organizations that make our work meaningful. Through DataBank Cares, we invest in causes that matter: from health and wellness to education, sustainability, and local community organizations.
We’re proud of what our team accomplished at DFW3, and we’re already looking forward to the next opportunity to give back.
Want to learn more about DataBank Cares and our community initiatives? Check out DataBank Digest to see how DataBankers go beyond the data center to give back to the communities where we live and work.
As enterprise infrastructure demands grow more complex, power density and operational reliability have moved to the top of the priority list. Yet what’s less discussed is the connectivity layer that can make or break performance at scale. This is where carrier hotels matter: a specialized class of data center facility whose connectivity capabilities go beyond what standard colocation can offer.
What makes a facility a carrier hotel comes down to who’s in it: telecommunications carriers, ISPs, and network operators, all with the specific goal of enabling network-to-network interconnection at scale. Organizations gain access to carrier choice, competitive pricing, and direct cloud reach that simply aren’t available in a standard colocation environment.
This article breaks down what carrier hotels are, how they work, and why they represent a meaningful upgrade over conventional colocation for enterprises with serious infrastructure requirements.
A Convergence Point for the World’s Networks
Carrier hotels emerged in the 1990s as the internet began its commercial expansion. Telecom providers needed a neutral, shared environment where they could exchange traffic with competing and complementary carriers without building redundant physical infrastructure across every major market. These facilities became the foundation of modern internet peering and transit.
Today, carrier hotels serve as the physical home for internet exchange points (IXPs), cloud on-ramps, and content delivery networks, creating a single location where networks, cloud providers, and content platforms can interconnect directly. That concentration reduces latency, eliminates unnecessary hops across third-party networks, and keeps traffic local when it doesn’t need to travel globally. The result is a faster, more resilient connectivity fabric that benefits every organization with a presence in or near that facility.
The concentration of carriers in a single location is what makes these facilities so powerful. Where a typical colocation site might offer access to a handful of network providers, a carrier hotel can host dozens — sometimes more than 100 — giving tenants an extraordinary range of connectivity options.
What Sets Carrier Hotels Apart
At the operational core of every carrier hotel is the meet-me room (MMR): a dedicated space where carriers physically cross-connect their infrastructure. MMRs enable fast, low-cost fiber connections between providers, which, for enterprises, translates into faster provisioning and more competitive pricing for the connectivity that powers cloud access, distributed workloads, and hybrid infrastructure.
The underlying infrastructure reflects those demands as well. Carrier hotels are built to support a high concentration of active networking equipment, with power and cooling infrastructure sized accordingly. Reliability standards are strict, and redundancy across power, cooling, and physical access is built in from the ground up.
Security and compliance requirements follow the same logic. Carrier hotels host infrastructure that is, in many cases, critical to regional and national communications networks. Access control, monitoring, and certifications are held to a higher standard as a result.
Why Enterprises and Cloud Users Choose Carrier Hotels
For enterprise IT teams, proximity to a carrier hotel, or presence within one, creates a measurable performance advantage. Latency-sensitive applications, including financial trading platforms, real-time communications, and AI inference workloads, perform better when the path between compute and network is as short as possible.
Carrier density also shifts negotiating leverage in the customer’s favor. When multiple providers compete for the same tenant in the same building, pricing becomes more transparent and procurement cycles shorten. Organizations can switch providers without a costly physical move, which changes the dynamic of every contract conversation.
Cloud connectivity is where carrier hotels deliver some of their most tangible value. Major hyperscalers, including AWS, Microsoft Azure, and Google Cloud, establish direct connect and private peering access within carrier hotel environments. That gives enterprises a private, low-latency path to cloud resources that bypasses the public internet entirely, strengthening both performance and security posture.
Why Location and Ecosystem Density Matter
Not all carrier hotels are created equal. A facility with 20 carriers offers meaningfully different value than one with 100. Ecosystem depth, measured by the number and variety of networks, cloud providers, and content delivery networks present in a facility, is one of the most important criteria when evaluating interconnection options.
Geographic positioning matters just as much. Carrier hotels in major metro markets typically sit at the crossroads of regional and long-haul fiber routes, giving tenants access to connectivity that spans continents, not just cities. For organizations with global operations, that reach is essential.
For enterprises navigating distributed infrastructure, hybrid cloud, and AI-driven workloads, the question isn’t just whether a data center can house the equipment. It’s whether it can connect it the way the business requires.
As enterprise workloads grow more distributed, spanning on-premises infrastructure, multiple cloud environments, and edge deployments, the carrier hotel shifts from a niche consideration to a strategic anchor. The ability to connect everything an organization runs, at the speed and reliability the business demands, starts with being in the right place.
The Right Facility Changes Everything
Carrier hotels represent a distinct class of infrastructure, and organizations that understand that distinction make better decisions about where they place their most demanding workloads. Connectivity depth, carrier choice, cloud reach, and geographic positioning all compound over time into real performance and cost advantages.
For enterprises navigating distributed infrastructure, hybrid cloud, and AI-driven workloads, the question isn’t just whether a data center can house the equipment. It’s whether it can connect it the way the business requires.
Looking to learn more about carrier hotels and the connectivity strategies behind high-performance enterprise infrastructure? Visit DataBank Digest for expert perspectives on the infrastructure decisions that matter most.
Anyone who has worked in IT long enough knows that “technical debt” has a well-deserved negative reputation. It’s usually the result of the shortcuts companies take, the duct tape solutions, the code that makes engineers wince. It’s the mess that accumulates when teams move fast, and eventually it starts slowing everything down.
Here’s what I’ve come to realize, though: there’s another way to think about it. Complaining about technical debt is a privilege that only growing companies get to experience. It’s evidence that you made it far enough to outgrow your early solutions. Think of it like looking back on decisions you made years ago. If nothing makes you cringe, you probably weren’t taking enough risks, or you simply haven’t grown.
Technical debt is what happens when a company builds something quickly to solve an immediate problem, knowing full well it won’t scale elegantly in the future. Think of it like renovating a house while people are living in it. You do what works now, even if it means you’ll need to redo it properly later. It’s like building your dream home in your 20s. You can’t predict who you’ll be later in life, and you’ll likely need to course correct at some point in the future.
The Right Team for the Wrong Moment
Small startups and large enterprises have fundamentally different needs. Startups need to move fast, find product-market fit, and innovate before someone else does. Large companies need to scale reliably, operate repeatably, and minimize risk. That journey from startup to enterprise almost always generates technical debt along the way. The solutions that get a company off the ground rarely hold up at scale, That’s not a failure of foresight, it’s just the nature of building something real under pressure.
Consider this common scenario. Imagine a small startup that builds a 10-person development team to develop a web-based product. The team is fantastic: highly functioning, great synergy, appropriate structure, history of working together, and just about every attribute that looks perfect on paper.
Yet despite seeming to check every box, the team turned out to be the wrong fit. They came from large organizations where they built highly engineered, market-research-driven solutions with quarterly development cycles. What the startup needed was the ability to move fast and iterate weekly, not quarterly. This kind of mismatch is easy to miss in the moment, even for experienced leaders focused on doing the right things.
The real cost shows up in what doesn’t get built. When a team is focused on engineering solutions for problems that don’t exist yet, the challenges that actually need solving get pushed aside. By the time they’re addressed, the opportunity has often already passed.
Embracing the Mess
In my current role at DataBank, I’m part of a small, self-contained team working on managed services solutions. We’re allowed to be the experts and make calls quickly, but we have to deliver—and we consistently do, with speed and pragmatism over perfection.
We’re creating solutions that prioritize speed and iteration over elegance. They may not be the most refined builds, but they solve real problems now and create a foundation we can improve on as we grow.
I couldn’t be more excited about it.
Because those future problems? They’re the ones worth having—signs that we succeeded, that we grew, that we moved fast enough to capture opportunity before it disappeared. Technical debt means you’ve scaled far enough to outgrow the solutions that got you here.
The Potential for New Technical Debt
There’s an interesting parallel with what’s happening in AI-assisted development right now. Non-technical people (myself included) are using AI coding tools to create fast solutions. The code isn’t always elegant or scalable, usually leading to so much AI slop. It’s what happens when the priority is shipping fast over building well, and any team moving quickly enough is likely to encounter it.
The question worth asking is whether AI-assisted code represents the same kind of luxury problem we’ve been discussing. I think it does.
The deeper question is whether experienced programmers will evolve into specialists who help AI-generated code scale elegantly, or whether AI development tools will simply advance to the point where the quality gap disappears. The answer is probably both. There will always be value in building things that hold up over time, and there will always be value in empowering more people to move faster. In the early stages of a product or service, speed matters most. But the craft of building things that scale never really goes away.
The Bigger Picture
None of this is an argument for building carelessly. It’s an argument for building appropriately for the stage a company is in. A three-person startup shouldn’t be building like they’re Google. They also shouldn’t feel ashamed when, three years later, they need to refactor the systems that got them to product-market fit.
The technical debt conversation tends to focus on what went wrong. A more useful question is what went right. The team moved fast enough to gain traction. They built solutions that worked for the problems they had, not the problems they might face someday. They earned the right to revisit that early code.
The next time an engineering team starts groaning about technical debt, consider celebrating it instead. The company made it. There are real problems worth solving. Those problems can now be addressed with the time and resources that simply weren’t available in the early days.
That’s not a burden. That’s a badge of honor.
Jason Rasmuson also contributed to this article.
Artificial intelligence workloads are reshaping data center infrastructure in ways the industry couldn’t have anticipated, and this transformation continues to evolve rapidly as we learn new things about AI. With large-scale deployments still emerging, each implementation teaches us more about how to manage data centers for these demanding workloads.
The challenge begins with fundamentally different power demands. Until now, most enterprise applications used relatively steady power consumption to run email servers, host websites, serve up real-time digital experiences, and manage customer transactions.
AI changes this equation completely. We are seeing that these workloads now experience intense oscillation as neural networks dynamically allocate computational resources across thousands of processing cores and activate different pathways during training cycles or inference tasks.
The result? Power consumption that can fluctuate by more than 50% in mere microseconds. This creates violent power spikes that rise and fall with each computational task and happen much faster than traditional infrastructure was designed to handle.
Power Infrastructure Under Pressure
The consequences can be immediate and expensive. When AI workloads spike power consumption in microsecond bursts, uninterruptible power supply (UPS) systems can fault and dump the load directly onto backup batteries.
This constant battery cycling from microbursts can be devastating where it occurs, potentially reducing battery lifespan by 50% or more and transforming predictable three-to-five-year replacement cycles into 18-month emergency replacements. In response, UPS vendors are actively exploring capacitors and other alternatives. This creates an evolving landscape of innovation for data center equipment as the industry continues learning how to address these unique challenges.
For data centers already operating with constrained budgets, these unexpected maintenance costs and the need for infrastructure upgrades can create overwhelming financial pressure.
The Cooling Conundrum: When Minutes Become Seconds
The cooling challenges are equally dramatic. Everything changes when power density hits approximately 40 kilowatts per rack—the practical limit for traditional air cooling. Beyond that threshold, liquid cooling becomes mandatory.
Yet, AI deployments aren’t stopping at 40kW. Industry roadmaps show NVIDIA and other vendors targeting 600 kilowatts to one megawatt per rack. This means that the vast majority of each rack’s power consumption will require direct liquid cooling to computer chips.
This triggers a domino effect of infrastructure challenges. Existing buildings often lack the physical piping infrastructure needed for liquid-to-chip cooling systems. Retrofitting buildings with chilled water systems, coolant distribution units, and supporting infrastructure represents a massive capital expense that exceeds many facilities’ budgets, while others just don’t have the space for such extensive upgrades.
Perhaps, most critically, the margin of error has collapsed. Traditional data center workloads gave operators 20 to 30 minutes to respond to cooling system failures before reaching critical temperatures. High-density AI workloads compress that window to two minutes or less. The thermal runaway risk is so severe that cooling systems now require their own backup power, thermal storage tanks acting as batteries for cooling, and unprecedented levels of redundancy.
Even when operators try to build adequate thermal storage, physics works against them. Every two minutes of cooling backup requires massive water tank scaling, and most existing facilities simply don’t have the physical space for the storage volumes that would provide meaningful protection.
These infrastructure requirements would have seemed excessive just a few years ago and may still seem excessive to those who haven’t experienced a cooling failure in a high-density AI environment.
Building for the AI Future: Strategic Infrastructure Solutions
Rather than being caught off guard, innovative data center operators are already planning and building the specialized infrastructure that AI workloads demand.
The industry response is moving on multiple fronts simultaneously: making hard economic decisions about retrofits, designing purpose-built AI facilities, and pioneering modular approaches that deliver flexibility without sacrificing efficiency.
The economics of retrofitting existing infrastructure are driving operators toward a different approach. While some facilities can accommodate AI workloads with targeted upgrades, the real innovation is happening with purpose-built facilities designed from the ground up for AI requirements.
These new data centers are optimized specifically for AI workload characteristics, incorporating power delivery systems engineered to handle rapid fluctuations and cooling architectures that scale from air to high-density liquid cooling as needed. The designs prioritize modularity and flexibility, allowing operators to configure spaces for different AI applications without traditional one-size-fits-all constraints.
The performance gains are significant. These facilities achieve higher computational density per square foot, more efficient power utilization, and cooling systems that respond dynamically to workload demands while incorporating redundancy designed specifically for AI’s shortened response times.
Modular Construction: Building as You Grow
Modular design is emerging as a key sustainability and economic strategy. Rather than constructing massive facilities all at once, operators can now build incrementally based on actual demand. Standardized components deliver economies of scale, similar to apartment building construction where identical units drive down per-unit costs. This also allows operators to pack more computing power into buildings without expanding physical footprints to city-block proportions.
From a sustainability perspective, this represents a practical balance. While reusing existing infrastructure would theoretically be more environmentally friendly, legacy data centers simply cannot handle modern AI workload requirements cost effectively. The new modular designs are inherently more efficient and reduce cooling dependencies, creating long-term environmental benefits that offset the initial construction impact.
Rethinking Efficiency: More Computing, Not Just More Power
Perhaps, most importantly, the industry is beginning to properly measure the true efficiency gains that AI workloads deliver. While it’s true that AI systems draw more power than traditional computing, they deliver significantly more computational capability per kilowatt consumed. Graphics Processing Units (GPUs) optimized for AI workloads can process far more operations using the same energy as traditional CPUs handling equivalent tasks.
This efficiency paradox creates powerful business incentives for continued optimization. Data center operators profit from maximizing the computational output per unit of power consumed, naturally aligning business objectives with energy efficiency goals. As operators deploy more AI-optimized infrastructure, they’re achieving better overall energy utilization compared to traditional computing approaches.
The Infrastructure Evolution Ahead
The transformation of data center infrastructure for AI represents both an immediate challenge and a long-term opportunity. Data center operators succeeding in this transition understand that AI workloads demand fundamentally different approaches: from managing microsecond power fluctuations and less than two-minute cooling windows to building purpose-built facilities with modular designs that scale incrementally.
The future won’t be exclusively AI-driven since traditional workloads will persist because AI infrastructure remains expensive. However, enterprises are strategically shifting portions of their operations to AI as they recognize efficiency gains that offset higher infrastructure costs. The data centers that emerge will be more efficient, more flexible, and better positioned for whatever computational demands come next.
[ez-toc]
What is interconnection? Interconnection is an over-arching term that refers to many different physical and virtual connections companies can select to exchange data, provide business continuity and customer services, and address specific business objectives. Interconnection in colocation data centers are vital for fast data exchange, reduced latency, improved network performance, and other benefits.
Yet, the term interconnection is often used in different ways. As a result, it’s easy to understand why there is some confusion related to interconnection today. It may also explain why there are so many frequently asked questions (FAQs) on this topic.
To help, this article will take a closer look at interconnection in colocation data centers. It will also include a detailed look at five different but commonly used interconnection approaches today.
Why Do We Need Interconnection?
Why do companies need interconnection? The first answer is that interconnection plays a major role in helping businesses become more agile and responsive. Interconnection services from colocation providers enables unprecedented flexibility to distribute computing resources and move intelligence closer to the point at which decisions are made.
Interconnection also enables organizations to directly connect their networks to reduce the number of hops data must take to reach its destination. This leads to reduced latency, faster data transfer speeds, and improved application performance. The right interconnection technology and strategy can be a critical advantage for latency-sensitive workloads like streaming services, real-time data analytics, and financial transactions.
It may be helpful to think of interconnection as an umbrella term to refer to many technologies capable of connecting networks to networks. However, it’s important to know the difference between each type. This can help you select the right technology for the right job to establish connectivity in the data center.
Let’s take a closer look at five types of interconnection services available in most data centers today.
Cross Connects
Cross Connects represent the most basic type of interconnection. This term generally refers to the physical and dedicated connection between two networks directly within the same data center. Cross Connects provide dedicated, point-to-point connectivity as well as the most reliable, efficient, and secure way to connect networks and infrastructure. They also deliver excellent reliability and low latency.
Internet Exchanges
An internet exchange, or internet exchange point (IXP), is essentially a network switch. Organizations connect to an IXP via a physical cross-connect, enabling them to link up with other IXP members, without the need for dedicated cabling (or cross connect) to each IXP member.
Companies use internet exchanges to set up peering with other networks linked to the IXP. They use the BGP protocol for peering sessions through a single physical link, once again eliminating the need for extra cables. This peering capability is a key advantage for interconnected entities like internet service providers, content delivery networks, other service providers, and enterprises. It helps them cut transit costs, boost capacity, and enhance network performance.
Private peering, on the other hand, occurs within a colocation facility, where two parties use separate network routers but establish a direct cross connect rather than using the IXP. This setup is advantageous when large traffic volumes are exchanged between networks, exceeding the capacity of a shared exchange point connection.
Data Center Interconnects (DCI)
A data center interconnect (DCI) is similar in theory to a cross connect but uses electronics, typically DWDM, to establish a point-to-point connection between two data centers so they can share resources or improve other operations such as load balancing. For example, a company could choose to connect two different networks in the same metro or in two different metros.
DCI can connect any data center whether it’s in close proximity or located a great distance apart. This may depend on the technology used to deliver the connectivity (Optical Networking, or Ethernet).
Internet Connectivity
As the term suggests, internet connectivity enables data center clients to access and use the internet — and vice versa — for internet users to quickly reach the websites and applications of data center clients. However, this goes far beyond a simple connection. There are several methods to deliver internet connectivity, including:
Dedicated Internet Access (DIA) that offers basic connectivity. (Burstable Internet Access offers connectivity with a usage-based billing method.
IP Transit, which is more sophisticated, leveraging the BGP protocol. This approach enables organizations to advertise their own IP prefixes and manage how routing information is utilized.
Cloud Connectivity
Cloud connectivity refers to a company’s ability to link its systems to a virtual environment hosted by public cloud providers such as AWS, Microsoft Azure, or Google Cloud Platform, enabling access to their data and workloads.
While businesses often have resources like computing power, storage, and services housed in a data center, their applications may reside in the cloud. For optimal performance, they require a secure, private connection between these environments to address challenges related to bandwidth, reliability, and security.
There are several approaches to establishing cloud connections:
VPN: Businesses can link virtual private clouds to remote networks using various VPN options, such as site-to-site VPNs, cloud provider-specific VPN solutions, or third-party VPN software.
Cloud on-ramps: These connections utilize network infrastructure deployed by cloud providers. However, they may not be universally available across all data centers due to cost constraints, especially in regions with many data centers. Companies located in facilities with cloud on-ramps can access them easily through a cross-connect.
Network as a Service (NaaS): Organizations in data centers without cloud on-ramps can use NaaS platforms to achieve similar connectivity. NaaS operates much like an IXP, acting as a switch to connect companies to various cloud on-ramps.
All these options are designed to help companies in colocation data center environments access public cloud services efficiently, reliably, and securely.
Optimizing Connectivity for Modern Businesses
Interconnection in data centers is crucial for businesses seeking to optimize their network infrastructure and reduce operational complexity. The evolving landscape of interconnection technologies offers businesses the flexibility to tailor their connectivity solutions to meet their specific needs and improve the way they manage their business.
DataBank recently published a white paper examining the reality of cloud repatriation, exploring why enterprises are moving workloads back from public cloud, the hidden challenges of repatriation itself, and strategies for avoiding these pitfalls altogether. To learn more, download “The Reality of Cloud Repatriation” now.
Over the past two posts, we’ve followed a story that’s playing out across enterprise IT.
In the first article, we looked at why 86% of CIOs are rethinking their cloud strategies, driven by unpredictable costs, compliance complexity, and support gaps that materialized only after significant cloud commitments were made.
That brings us to the most important question of the series: How do you avoid ending up there in the first place?
The answer isn’t to avoid cloud. It’s to stop treating infrastructure decisions as permanent, and start designing for flexibility from the beginning.
The Real Cost of Not Planning Ahead
Most organizations don’t set out to create vendor lock-in. It accumulates gradually. A team adopts a managed database service because it’s convenient. Another builds on a proprietary container orchestration platform because the documentation is good. Over time, these choices compound, and what began as a series of reasonable shortcuts becomes an architecture that’s expensive and disruptive to undo.
The organizations that successfully avoid painful repatriation projects share a common trait: They made deliberate decisions about where and how to use vendor-specific features rather than defaulting to whatever was easiest in the moment. That discipline is harder to maintain than it sounds, because cloud providers are very good at making their proprietary services attractive. Convenience is a feature, and it’s designed to deepen dependency.
Build with Portability in Mind
Vendor agnosticism doesn’t mean rejecting cloud providers or their ecosystems. It means making conscious trade-offs about portability from the start.
In practice, this looks like choosing containerization with Kubernetes over proprietary orchestration, using open-source databases rather than managed database services with limited export options, and relying on infrastructure-as-code tools that work across environments rather than cloud-specific tooling that ties you to one provider. At the application level, it means avoiding tight coupling to proprietary APIs, using abstraction layers, and documenting dependencies so future teams understand what it would take to change course.
The upfront investment in portable architecture pays dividends when business needs shift or when a vendor’s pricing and policies move in unfavorable directions. Those situations are difficult to predict but nearly impossible to avoid over a long enough timeline.
Choose Partners for Flexibility, Not Just Features
Technical architecture is only half the equation. Partner selection matters just as much.
The right infrastructure partner offers a full spectrum of deployment options, including colocation, private cloud, bare metal, managed services, and seamless public cloud connectivity, so that as workload requirements evolve, organizations can adapt without changing partners or starting over. That kind of flexibility removes the infrastructure layer as a constraint on business decisions.
Pricing transparency deserves the same scrutiny as technical capabilities. Cloud providers’ pricing structures aren’t necessarily deceptive, but they’re often incomplete. The scenarios that generate the largest bills, such as high-volume data transfers, complex scaling patterns, and sustained high utilization, may not be front and center in initial conversations. Asking detailed questions upfront and expecting candid answers about worst-case cost scenarios is a reasonable expectation from any infrastructure partner worth working with.
For organizations in regulated industries, compliance certifications are equally important. A partner with existing FedRAMP, HIPAA, PCI DSS, and SOC 2 certifications dramatically reduces the burden of implementing controls independently in public cloud environments, which is one of the most commonly underestimated costs in cloud adoption.
Match Workloads to the Right Environment
Not every workload belongs in the same place, and the organizations that manage infrastructure costs most effectively are the ones that know the difference.
Public cloud is genuinely well-suited for applications with highly variable or unpredictable demand, development and testing environments that benefit from fast provisioning, and workloads that require global geographic distribution. These are the use cases where elastic scaling and pay-as-you-go economics deliver real value.
The calculus looks different for stable production workloads with predictable resource requirements, latency-sensitive applications, data-intensive workloads that generate significant egress fees, and systems subject to strict compliance mandates. For these, colocation and private cloud environments often deliver better performance at lower total cost, once the full picture is accounted for.
That last point is worth emphasizing. Total cost of ownership analyses need to go beyond monthly infrastructure bills to include data transfer costs, management overhead, compliance implementation, support quality, and the long-term cost of reduced flexibility. Organizations that run honest TCO comparisons across deployment models frequently discover that public cloud economics look very different at scale than they do during early pilots.
Plan for an Infrastructure Strategy That Can Evolve
Infrastructure decisions shouldn’t be treated as permanent. Business requirements change. Technology evolves. Vendor landscapes shift in ways that are impossible to anticipate years in advance.
Organizations that navigate this well build regular infrastructure assessments into their planning cadence, examining both technical performance and financial efficiency to identify workloads that have outgrown their current environments. They invest in maintaining in-house infrastructure expertise even when relying heavily on managed services. And they cultivate relationships with multiple infrastructure partners rather than concentrating dependency on a single vendor.
The goal isn’t to predict every future requirement. It’s to preserve the ability to adapt when requirements change, without facing the kind of costly, disruptive migrations that have sent so many organizations searching for alternatives to their initial cloud decisions.
Prevention as Strategy
The rise of cloud repatriation isn’t a story about cloud failing. It’s a story about infrastructure maturity, with organizations learning, sometimes at significant cost, that no single approach works for every workload at every stage of growth.
The good news is that the lessons are learnable before the pain sets in. By prioritizing portability in application design, choosing partners that offer genuine flexibility, making deliberate workload placement decisions, and building in regular reassessment, organizations can use cloud strategically while maintaining the freedom to evolve.
DataBank is built around this kind of flexibility, offering colocation, private cloud, bare metal, and managed services alongside direct cloud connectivity, so customers can optimize each workload for its specific requirements. Because the best infrastructure strategy is one that doesn’t box you in.
Sustainability has become considerably more complicated for the data center industry heading into 2026. Political shifts, policy changes, and other new market dynamics are creating an environment where progress may become harder to achieve.
Here are five predictions for how new trends and market forces will reshape data center sustainability in 2026.
Prediction #1: Greenhushing Will Replace Transparency
The trend toward greater sustainability and transparency will somewhat reverse in 2026. We’re already seeing cases where companies across many different industries are pulling back from public commitments and reducing visibility into their environmental programs—a trend now known as “greenhushing.”
This isn’t because sustainability efforts are stopping or even slowing down. It’s because the political and legal environment has made too much transparency risky. A large hyperscale cloud provider recently removed its net zero target from its website despite continuing to work toward this goal. In many other cases, terms like “ESG” are being rebranded to avoid too much political scrutiny.
This creates a dilemma for data center operators. Customers’ RFPs still require renewable energy commitments and sustainability certifications, and investors still evaluate ESG performance. Yet, the appetite for public messaging has diminished significantly.
The result is a disconnect where meaningful sustainability work continues behind the scenes while public communication will become more cautious or disappear completely. In response, data centers will need to balance legitimate customer and investor requirements against the risks of visible or perceived ESG-related advocacy in 2026.
Prediction #2: The Renewable Energy Cliff Draws Closer
Federal tax incentives are continuing to drive a surge in solar and wind deployments through mid-2026, but chances are good that the momentum will hit a wall soon after. Projects must either (1) begin construction by mid-2026 and be placed into service by 2030, or (2) be placed into service by the end of 2027 to receive clean energy tax credits.
This compressed timeline is forcing data center operators to accelerate procurement decisions and lock in renewable power agreements now or face a significantly different market landscape to address renewable and clean energy targets.
The consequences may extend beyond individual project timelines. When these incentives disappear, new solar and wind capacity will slow while older coal plants will remain operational longer than planned. Data center operators working toward net zero targets may find few options for new renewable power purchases.
Companies will likely turn to longer-term renewable energy procurement now, while those who don’t may face higher costs and limited supply in a constrained market. The window for taking advantage of current renewable energy economics is closing fast.
Prediction #3: Market Consolidation Follows the Power
The data center boom attracted a flood of new entrants over the past two years. Developers from other sectors recognized opportunity and rushed in, acquiring land and requesting power without always securing the infrastructure or capital needed to execute. This speculative activity is creating artificial scarcity and inflated competition for resources.
Yet not all these companies will survive 2026. The combination of limited available land, constrained power supply, and substantial capital requirements will force weaker players out. Chances are good that companies that purchased property without confirmed power access will struggle to deliver. Those without deep pockets or committed customers will find themselves unable to compete.
The resulting consolidation will benefit those established operators with proven execution capabilities. As speculative players exit, pressure on land and power resources should ease. The market correction will be painful for some, but it should ultimately push the industry toward more sustainable growth patterns built on real demand instead of speculative bets.
Prediction #4: Cooling Strategies Shift Toward Water Conservation
Data center operators are increasingly adopting waterless cooling technologies and closed-loop systems as part of water-conscious facility design strategies in areas of high water stress. Traditional evaporative cooling remains energy efficient in suitable climates and appropriate in many locations, but operators are recognizing that cooling choices should match local conditions rather than following a one-size-fits-all approach.
Closed-loop chilled water systems are becoming more popular because they recirculate coolant continuously with minimal or no water loss. Some facilities are exploring entirely waterless approaches using advanced air cooling or alternative fluids. However, local water availability is becoming an increasingly important factor in that cost equation. In water-stressed regions or communities particularly concerned about water usage, the economic and reputational costs of evaporative cooling may outweigh its energy efficiency advantages, making closed-loop and waterless systems more attractive.
The key change is strategic thinking about cooling decisions. Rather than defaulting to a single approach across all facilities, operators are evaluating local water availability and community concerns when designing cooling infrastructure. This geographic sensitivity to water resources represents smarter engineering practice as data centers balance energy efficiency against environmental stewardship and community relations.
Prediction #5: Nuclear, Geothermal, and Energy Storage Gain Momentum
While solar and wind incentives face expiration, nuclear power, geothermal energy, and energy storage systems retained their tax credits, creating a policy environment that favors these technologies through 2027 and beyond.
Data center operators are responding accordingly. Nuclear and geothermal power offer the constant baseload capacity that facilities require, without the intermittency challenges of renewables. Energy storage systems provide grid flexibility and backup power while supporting renewable integration. These technologies align with customers’ sustainability requirements while offering operational advantages.
The challenge is getting these technologies deployed quickly enough. Small modular reactors and advanced nuclear technologies show promise but face lengthy development and approval processes. Energy storage supply chains need domestic scaling to meet demand. Despite these hurdles, expect accelerated investment in both technologies as the renewable incentive cliff approaches and operators seek alternative paths to clean energy goals.
Preparing for What Comes Next
Data center operators face a different sustainability situation in 2026 than anyone expected two years ago, but the core business drivers haven’t changed.
The operators who succeed will be those who stay focused on these fundamentals and keep their heads down when necessary, building the right infrastructure for local conditions, and making decisions based on what customers request rather than whatever’s dominating the news cycle. When politics change again, the companies that spent their time executing will be better off than those who spent it talking.
Want to stay ahead of the sustainability trends reshaping the data center industry? Check out DataBank Digest for more insights on data center industry trends and infrastructure strategy.
When Anthony Hayes, DataBank’s Critical Facility Manager in Atlanta, received a call from Dexter Edmonds of Opportunity Runway asking if DataBank would host a career exploration event, he didn’t hesitate.
The mission was simple but powerful: Open DataBank’s doors to young people, pull back the curtain on what data centers are, and show them that lucrative, fulfilling careers exist beyond the traditional four-year college path.
The event served two purposes. It would counter misconceptions about the data center industry while opening doors for the next generation. It also gave Hayes a chance to give back in a meaningful way. “What good is it for me to have this knowledge and these skills if I don’t share them?” Hayes said. “I wanted to tell my story, share my journey, and give young people different paths to success.”
Beyond the Headlines
The event, held on a Saturday at one of DataBank’s Atlanta facilities, drew nearly 20 young people eager to learn about an industry many had never considered.
For Hayes, it was a chance to move past the headlines and misconceptions about data centers –especially those related to water consumption and environmental impact— and focus on what matters most: the opportunities these facilities create for communities.
“A lot of the rhetoric about data centers comes from people who don’t understand the technology,” Hayes explained. “We wanted to show them real examples: what closed-loop cooling systems actually mean, how modern data centers operate, and most importantly, the career paths available in this industry.”
A Team Effort
The day featured multiple components designed to give attendees a comprehensive view of data center careers.
A data center industry expert from Method Experts, a training organization dedicated to equipping operators and technicians in mission-critical environments with essential skills for safety and operational excellence, delivered an educational session on data center fundamentals, their diverse applications, and the wide range of career paths available. He covered everything from physical security and cybersecurity to MEP (mechanical, electrical, and plumbing), operations, and rack-and-stack positions.
Brian Wilkerson from PRT Staffing, a placement service that works with the industry, provided lunch for attendees and even brought his 15-year-old son to the event—a powerful statement about the real conversations families are having about alternative career paths.
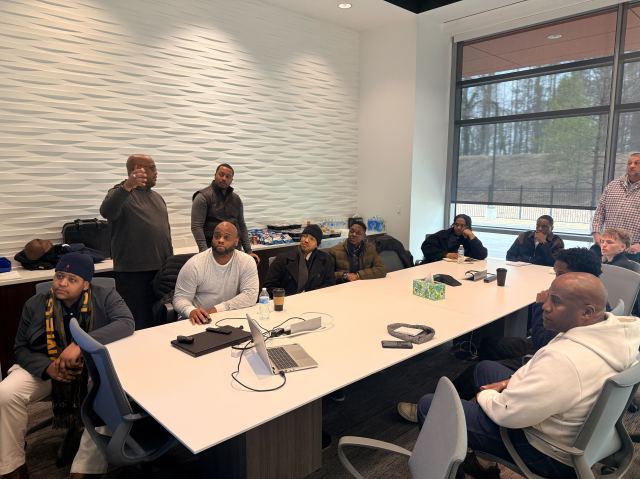
In this session, DataBank employees and data center experts presented career opportunities to students interested in learning more about the data center industry.
Hayes also invited members of his own team, Leon LaMar III and Clyde Ward, to share their personal journeys into the data center field. “Everybody in a data center has a unique story about how they got there,” Hayes said. “We’re in a field that didn’t exist 30 years ago, and now it’s exploding with opportunities young people may not even know exist.”
The Eye-Opening Reality
Hayes made a compelling case when he compared career paths side by side. The traditional college route often means four years of debt accumulation for a degree that might yield a $60,000 starting annual salary. Meanwhile, trade paths like becoming a journeyman or full electrician offer a dramatically different trajectory.
“You can join the IBEW, pay union dues, and get paid to learn,” Hayes told the group. “In the same four years someone else is in college, you can complete your training and come out making $45 to $55 an hour, which is close to six figures right from the gate.”
Hayes was also careful to note that choosing technical training doesn’t mean abandoning education entirely. Workers can return to school later to develop other skills like professional communication and presentation abilities. “The hard part is the technical knowledge,” he explained. “Once you have that, you can focus on perfecting your soft skills and positioning yourself for bigger roles over the years.”
The message clearly struck a chord. Many attendees connected with Hayes on LinkedIn after the event, staying behind to ask questions about what he looks for when hiring, whether he hires people without experience, and how they could break into the industry.
“The eye-opening realization that you don’t have to go to college but can still make real money,” Hayes said. “That was the biggest thing they took away.”
Creating Legacy
The event held special significance for Hayes. His own children are in high school, navigating similar decisions about their futures.
“It was an opportunity to show them that community is important, and that it’s important to have leaders who don’t gatekeep,” he said. “Your path might be different from mine, but it doesn’t hurt for you to understand my path and see there’s opportunities for you.”
Hayes also appreciates working for a company that actively supports community initiatives like this. “I really enjoy working for DataBank,” he said. “I’ve worked in toxic work environments before. This is so far from that. There’s a strong culture here that values giving back and investing in the communities where we operate, and that matters.”
Looking Ahead
The Atlanta event is just the beginning. Hayes continues to represent DataBank at career fairs and community events, partnering with organizations like Opportunity Runway to connect with young people exploring their career options.
“When we open our doors and share our story, we create pathways for others and strengthen the communities we call home,” Hayes said. “That’s what being a good neighbor really means.”
Want to see more stories about DataBank’s community involvement and industry leadership? Check out DataBank Digest for more insights on data center industry trends and infrastructure strategy.
It’s been a busy start to the year as evidenced that I’m writing this in February. After a record year of data center leasing and unprecedented investment announcements, some fundamental questions remain unanswered:
What is the actual pace of enterprise AI adoption?
How will companies like OpenAI and Anthropic meet their massive infrastructure commitments?
Can the power grid keep pace with amount of capacity coming online?
Which players have the capital and execution capability to survive tightening financial markets and increasing development costs?
These aren’t small questions, and while in some cases the answers are emerging, there is still a lot uncertainty.
I don’t expect 2026 will be the year of breakthroughs and think it will look and feel a lot like 2025. Yet the gap between ambitious announcements and financial reality will come into much sharper focus.
Here are my thoughts for what’s ahead for the data center industry for 2026.
Enterprise Colocation Demand Will Remain Strong
Despite economic headwinds including tariffs, slowing employment, interest rate questions, and widespread economic uncertainty, enterprise customers will continue investing heavily in technology infrastructure.
We signed a record number of multi-megawatt colocation deals in 2025, and we see that momentum continuing in 2026. Interestingly, this enterprise demand appears largely decoupled from the AI hype cycle. Yes, we are seeing some enterprise GPU deployments, but the bulk of what’s coming into our data centers are still CPUs and traditional compute/storage/network gear.
While AI infrastructure players grab headlines with gigawatt-scale deployments, established enterprise customers are quietly driving steady, sustainable growth in the colocation market. Enterprise customers prioritize reliability, flexibility of solutions, and proven operational expertise over gigawatt-scale campuses. Their needs may be less dramatic than AI training clusters, but they represent predictable, diversified, long-term revenue. For operators focused on this segment, 2026 looks healthy.
Financing Will Become Increasingly Difficult
The amount of capital being consumed by AI companies and data center developers has reached unprecedented levels.
There are more data center developments and companies in existence today than at any other time in our sector’s history. What do they all have in common? They all need cash to build.
This shift will hit newcomers the hardest. The high number of new real estate developers and newly minted data center operators who have entered the market over the past two years will find it increasing difficult to secure the capital needed to advance their developments.
The Power Story Will Escalate
According to industry reports, the data center industry leased over 15 gigawatts in 2025. The catch? Almost none of that capacity actually came online in 2025. It’s all scheduled to arrive in late 2026 and 2027, which means a massive surge in electricity consumption is about to hit the grid.
Meanwhile, supply remains constrained due to the current administration’s policies throttling near-term renewable energy projects and the long lead times required for natural gas and nuclear generation. The result is straightforward economics: constrained supply meeting sharply increased demand. Electricity prices will continue to rise into 2026 and beyond. This means that accessing power will become more difficult and expensive, and utilities will prioritize established players over new entrants.
Enterprise AI Adoption Will Continue to Be Gradual
Enterprise AI adoption will remain incremental in 2026. Expect two steps forward, one step back. There will be no watershed moment where AI suddenly transforms how businesses operate at scale, driving enterprise AI adoption to accelerate exponentially.
The reason is fundamental: AI is extremely powerful but difficult to control precisely. Businesses need predictable, foolproof outcomes from their systems. The current generation of LLMs delivers non-deterministic results. That tension makes enterprise integration genuinely challenging, not just a matter of overcoming adoption curves or change management.
Companies will continue experimenting, investing, and learning where AI can drive ROI in 2026. Some will find valuable applications and use cases; others will shutter projects and reduce spend. AI will be transformative, but the journey will take years.
Want more perspectives on where the data center industry is headed? Check out DataBank Digest for more insights on data center industry trends and infrastructure strategy.